Schema markup for AEO works by making your facts machine-readable and consistent, not by directly feeding text to ChatGPT or Perplexity. Most AI engines read your rendered page text, not your JSON-LD. What schema actually does is resolve your entity, confirm your author and organisation identity, and feed Google’s Knowledge Graph, which is what decides whether you’re a source worth pulling into an AI Overview in the first place. Add schema that contradicts your visible text and you make things worse.
That distinction matters, because it changes what you implement and in what order. Here’s what actually applies to a B2B SaaS or e-commerce site, sequenced by priority.
Does schema markup for AEO actually get you cited by AI engines?
Indirectly, and the mechanism is worth understanding before you spend a sprint on it.
An LLM answering a question is working from crawled page text and from search results it was handed. It is not parsing your Product schema and deciding to cite you because your aggregateRating looked good. The visible sentence that answers the question is what gets lifted — which is why the work that actually moves the needle is getting cited by ChatGPT and Perplexity through the content itself.
Schema does three things that make that lift more likely:
- It disambiguates your entity. When your Organization markup states your name, logo, founding date and sameAs links to LinkedIn, Crunchbase and your GitHub org, machines stop guessing whether “Acme” is your company or three other ones.
- It attaches authorship to a real person with credentials, which is the machine-readable half of E-E-A-T and topical authority.
- It forces you to state facts explicitly. Price, availability, author, publication date, applicable operating system. Pages that state facts plainly are the pages that get quoted.
The contrarian bit: structured data GEO advice that promises “add FAQ schema Markup and AI will cite you” has the arrow backwards. Schema is a consistency layer over content that’s already correct. If your page hedges and never states an answer outright, no amount of JSON-LD saves it — which is the first principle of any serious answer engine optimisation programme.
Which schema types apply to which pages?
Map it by page type before you write a line of code.
| Page type | Primary schema | Add if relevant |
| Homepage | Organization | WebSite, BreadcrumbList |
| Product / feature page (SaaS) | SoftwareApplication | Offer, AggregateRating |
| Pricing page | Product with Offer | PriceSpecification |
| E-commerce PDP | Product with Offer | Review, AggregateRating, shipping and return details |
| Category / collection | CollectionPage | ItemList, BreadcrumbList |
| Blog post or guide | Article or TechArticle | Person as author, FAQPage |
| Docs and help pages | TechArticle | HowTo, FAQPage |
| Case study | Article | Organization as about |
| Contact / office pages | LocalBusiness | PostalAddress, OpeningHoursSpecification |
One caveat on that last row. If you run city or branch pages, the LocalBusiness block has to match the name, address and phone number you’ve published everywhere else — the same NAP consistency rule that governs local SEO. A schema block that disagrees with your Google Business Profile is worse than no block at all.
Two honest notes. Google restricted FAQ rich results to authoritative government and health sites back in 2023, and dropped HowTo rich results around the same time. Any FAQ schema guide promising you rich snippets from FAQPage is out of date.
You should still mark up FAQs. You just shouldn’t expect a visual reward for it. The value now is machine-readable Q&A pairing, which is exactly the shape AI answers are built from — and the same question-and-answer structure that voice search optimisation depends on.
The implementation checklist, in priority order
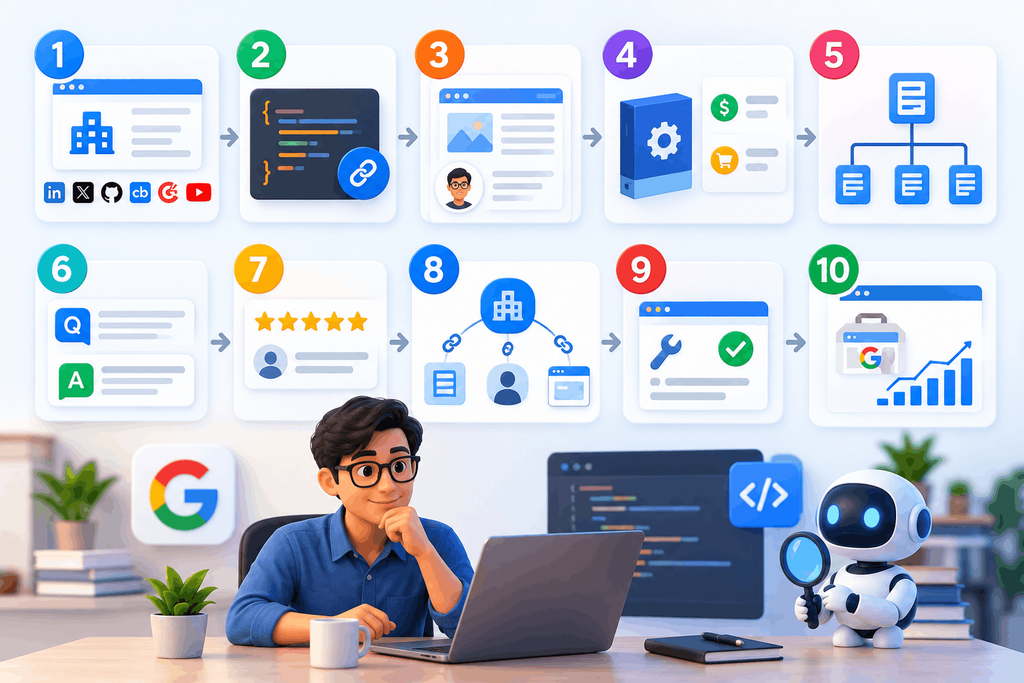
Work through these in sequence. Each step assumes the previous one is done.
- Mark up your Organization on the homepage first. Include name, url, logo, foundingDate, contactPoint, and a sameAs array pointing to every profile you control: LinkedIn, X, GitHub, Crunchbase, G2, your YouTube channel. This is your entity anchor and everything else references it.
- Give each entity a stable @id. Use a URI like https://yoursite.com/#organization. Not optional, and covered properly in the next section.
- Add Article or TechArticle to every content page, with a real Person as author. Give the author name, jobTitle, url pointing at a genuine author bio page, plus knowsAbout and sameAs to their LinkedIn. An author field containing a string, or worse your company name, wastes the strongest E-E-A-T signal you have. If you’re running a serious content marketing programme, build one Person entity per writer and reuse it.
- Add Product or SoftwareApplication to money pages. For SaaS, SoftwareApplication with applicationCategory, operatingSystem and an Offer carrying price and priceCurrency. For e-commerce, Product with Offer including price, priceCurrency, availability and itemCondition.
- Add BreadcrumbList sitewide. Cheap, still earns a visible search result change, and helps machines understand your hierarchy.
- Add FAQPage only where real Q&A exists on the visible page. Every question and answer in the markup must appear as visible text. No rich result, but the structure is worth having.
- Add AggregateRating only if reviews are genuinely displayed on that page. Marking up ratings you don’t show is a spam policy violation and it draws manual actions. Pull the numbers from a real review and reputation management process, not from a spreadsheet nobody updates.
- Wire the graph together with @id references. Article references its publisher by the Organization’s @id, isPartOf the WebSite, mainEntityOfPage the WebPage.
- Validate everything twice. Google’s Rich Results Test for eligibility, validator.schema.org for correctness. They catch different problems.
- Watch Search Console enhancement reports for three weeks. Price mismatches and missing required fields show up there before you’d ever notice them yourself.
How do you connect the pieces so machines resolve one entity?
This is the step almost everyone skips, and it’s the one that turns scattered markup into something useful.
Most sites publish four disconnected blocks: an Organization block, an Article block, a WebSite block, a Breadcrumb block. Nothing references anything else, so a parser sees four unrelated objects and has to infer the relationships.
Use a single @graph with stable @id URIs instead:
{
“@context”: “https://schema.org”,
“@graph”: [
{
“@type”: “Organization”,
“@id”: “https://example.com/#organization”,
“name”: “Example Analytics”,
“url”: “https://example.com/”,
“sameAs”: [
“https://www.linkedin.com/company/example-analytics”,
“https://github.com/example-analytics”
]
},
{
“@type”: “TechArticle”,
“@id”: “https://example.com/guides/event-tracking/#article”,
“headline”: “How event tracking works”,
“publisher”: { “@id”: “https://example.com/#organization” },
“author”: { “@id”: “https://example.com/team/priya/#person” }
},
{
“@type”: “Person”,
“@id”: “https://example.com/team/priya/#person”,
“name”: “Priya Menon”,
“jobTitle”: “Head of Data”,
“knowsAbout”: [“product analytics”, “event schema design”],
“sameAs”: [“https://www.linkedin.com/in/priyamenon”]
}
]
}
Now the article, the company and the author are one connected object. That’s what JSON-LD for AI search is actually good for, and it’s the difference between markup that validates and markup that resolves.
How do you verify it’s working?
Rich Results Test tells you whether Google sees a supported feature. It says nothing about correctness beyond that, and it silently ignores properties Google doesn’t use.
Run validator.schema.org as well. It flags invalid property names and wrong value types that Google’s tool passes over, and those errors matter for any parser that isn’t Google’s.
Then check what a non-JavaScript crawler sees. curl your page and search the raw HTML for application/ld+json. If your schema is injected by Google Tag Manager, it won’t be there. Google usually still picks it up after rendering, but most LLM crawlers don’t execute JavaScript, so GTM-injected schema is invisible to exactly the engines you built it for. Put it in the server-rendered HTML.
What actually goes wrong
Two conflicting Organization blocks. Your CMS plugin outputs one, a developer hand-coded another, and they disagree on the company name. Search your rendered HTML for every ld+json block before adding a new one.
Schema that doesn’t match visible text. FAQ answers only in the markup, a price in schema that’s different from the price on the page after a sale went live. Search Console flags the price one within days.
Author as a string. “author”: “Admin” is the single most common waste I see on SaaS blogs. It costs twenty minutes to build a real Person entity per writer and reuse it by @id.
Treating schema as the project. A page with perfect markup and a vague, hedged answer will lose to a page with no markup that states the answer in one clear sentence. Fix the sentence first, then the technical SEO layer underneath it, then the markup.
Make Your Content AI-Ready/h3>
Use schema markup to help search engines understand your content.
Optimize Your Schema No obligation. Straight talk only.Frequently asked questions
Do ChatGPT and Perplexity read schema markup?
Not meaningfully. Both work primarily from rendered page text and from search results supplied to them. Schema influences AI visibility indirectly, by shaping how Google’s Knowledge Graph understands your entity and by forcing your facts to be stated explicitly and consistently. Treat it as a supporting layer, not a direct input — if you’re starting from zero, read what answer engine optimisation actually is before you touch JSON-LD.
Is FAQ schema still worth adding in 2026?
Yes, but not for rich results. Google limited FAQ rich results to authoritative government and health sites in 2023. The remaining value is the machine-readable question-and-answer structure, which matches the shape AI answers are assembled from, and the discipline of writing genuine standalone answers on the page.
Should schema go in the HTML or through Google Tag Manager?
Server-rendered HTML. Google generally renders GTM-injected JSON-LD, but most AI crawlers don’t run JavaScript, so anything injected client-side is invisible to them. If GTM is your only option today, treat it as temporary.
How long before schema changes show any effect?
Google usually reflects markup within days to a few weeks of recrawl. Entity-level effects, meaning how consistently you’re recognised as the same organisation across the web, build over months and depend as much on your sameAs profiles being accurate as on the markup itself.
Can bad schema hurt rankings?
Markup that misrepresents page content can, through manual actions. Marked-up ratings that aren’t displayed, FAQ answers that exist only in JSON-LD, and prices that don’t match are the three that draw penalties. Incomplete or unsupported markup is usually just ignored.